
Regular tickets are now sold out for Latent Space LIVE! at NeurIPS! We have just announced our last speaker and newest track, friend of the pod Nathan Lambert who will be recapping 2024 in Reasoning Models like o1! We opened up a handful of late bird tickets for those who are deciding now — use code DISCORDGANG if you need it. See you in Vancouver!
We’ve been sitting on our ICML recordings for a while (from today’s first-ever SOLO guest cohost, Brittany Walker), and in light of Sora Turbo’s launch (blogpost, tutorials) today, we figured it would be a good time to drop part one which had been gearing up to be a deep dive into the state of generative video worldsim, with a seamless transition to vision (the opposite modality), and finally robots (their ultimate application).
Sora, Genie, and the field of Generative Video World Simulators
Bill Peebles, author of Diffusion Transformers, gave his most recent Sora talk at ICML, which begins our episode:

Something that is often asked about Sora is how much inductive biases were introduced to achieve these results. Bill references the same principles brought by Hyung Won Chung from the o1 team - “sooner or later those biases come back to bite you”.

We also recommend these reads from throughout 2024 on Sora.
Lilian Weng’s literature review of Video Diffusion Models
Estimates of 100k-700k H100s needed to serve Sora (not Turbo)
Artist guides on using Sora for professional storytelling
Google DeepMind had a remarkably strong presence at ICML on Video Generation Models, winning TWO Best Paper awards for:
Genie: Generative Interactive Environments (covered in oral, poster, and workshop)
We end this part by taking in Tali Dekel’s talk on The Future of Video Generation: Beyond Data and Scale.

Part 2: Generative Modeling and Diffusion
Since 2023, Sander Dieleman’s perspectives (blogpost, tweet) on diffusion as “spectral autoregression in the frequency domain” while working on Imagen and Veo have caught the public imagination, so we highlight his talk:

Then we go to Ben Poole for his talk on Inferring 3D Structure with 2D Priors, including his work on NeRFs and DreamFusion:

Then we investigate two flow matching papers - one from the Flow Matching co-authors - Ricky T. Q. Chen (FAIR, Meta)

And how it is implemented in Stable Diffusion 3 with Scaling Rectified Flow Transformers for High-Resolution Image Synthesis

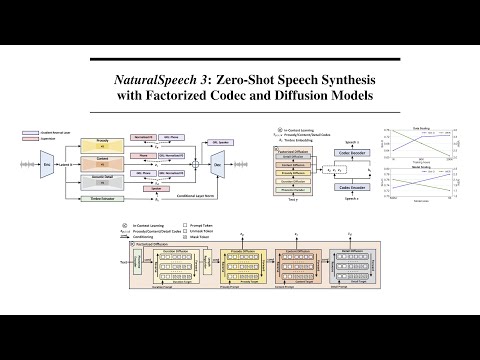
Our last hit on Diffusion is a couple of oral presentations on speech, which we leave you to explore via our audio podcast
Part 3: Vision
The ICML Test of Time winner was DeCAF, which Trevor Darrell notably called “the OG vision foundation model”.

Lucas Beyer’s talk on “Vision in the age of LLMs — a data-centric perspective” was also well received online, and he talked about his journey from Vision Transformers to PaliGemma.

We give special honorable mention to MLLM-as-a-Judge: Assessing Multimodal LLM-as-a-Judge with Vision-Language Benchmark.
Part 4: Reinforcement Learning and Robotics
We segue vision into robotics with the help of Ashley Edwards, whose work on both the Gato and the Genie teams at Deepmind is summarized in Learning actions, policies, rewards, and environments from videos alone.

Brittany highlighted two poster session papers:
• Behavior Generation with Latent Actions
We also recommend Lerrel Pinto’s On Building General-Purpose Robots
• PIVOT: Iterative Visual Prompting Elicits Actionable Knowledge for VLMs
However we must give the lion’s share of space to Chelsea Finn, now founder of Physical Intelligence, who gave FOUR talks on
special mention to PI colleague Sergey Levine on Robotic Foundation Models
We end the podcast with a position paper that links generative environments and RL/robotics: Automatic Environment Shaping is the Next Frontier in RL.

Timestamps
00:00:00 Intros
00:02:43 Sora - Bill Peebles
00:44:52 Genie: Generative Interactive Environments
01:00:17 Genie interview
01:12:33 VideoPoet: A Large Language Model for Zero-Shot Video Generation
01:30:51 VideoPoet interview - Dan Kondratyuk
01:42:00 Tali Dekel - The Future of Video Generation: Beyond Data and Scale.
02:27:07 Sander Dieleman - Wading through the noise: an intuitive look at diffusion models
03:06:20 Ben Poole - Inferring 3D Structure with 2D Priors
03:30:30 Ricky Chen - Flow Matching
04:00:03 Patrick Esser - Stable Diffusion 3
04:14:30 NaturalSpeech 3: Zero-Shot Speech Synthesis with Factorized Codec and Diffusion Models
04:27:00 Speech Self-Supervised Learning Using Diffusion Model Synthetic Data
04:39:00 ICML Test of Time winner: DeCAF
05:03:40 Lucas Beyer: “Vision in the age of LLMs — a data-centric perspective”
05:42:00 Ashley Edwards: Learning actions, policies, rewards, and environments from videos alone.
06:03:30 Behavior Generation with Latent Actions interview
06:09:52 Chelsea Finn: "What robots have taught me about machine learning"
06:56:00 Position: Automatic Environment Shaping is the Next Frontier in RL