

GPT-6 Astra, the first Stargate and lightly looped supermodel from OpenAI, launched today, cleanly beating Fable 5.1 on many metrics including completely saturating the hardest versions of FrontierMath (97.6%) and ARC-AGI-3 (99.9%). Lots of demos will focus on typical talk tracks like the computer use to the Pokemon playing to Blender to the scientific and cybersafety benchmarks (system card). Greg says AGI is here, and Jakub says it is finally the Automated AI Research Intern he wanted.
We aren’t qualified to talk about those, but we got early access and threw it at every practical, real-life task we could think of. After burning over 20B tokens of Astra, we can confirm the most surprising finding: GPT-6 Astra is one of a new class of models1 that are fully capable AI Engineers in their own right. They now help you choose and train models, label data (both helping you label and then using your labels for active learning, like SAM), keep pipelines saturated, instrument and read logs, deploy and debug entire systems in one shot, fan out and command and eval subagents (including agents running other models), and keep coherence over billions of tokens of a single agent thread.
Raising Your Ambitions
We’ve written before about the high-return activity of raising your aspirations for LLMs. Our experience has made us exponentially more ambitious than we have ever been. Over the past month, we went from prompting humans for a fun “Kill My SaaS” competition2, to building a dozen internal/personal tools, including 4 previously paid SaaS tools, fully redesigned my personal site, made an incomplete but functional replacement of GitHub + Vercel, trained game AI for a strategy board game with 10,000x more legal moves than Go, saved tens of thousands of dollars in personal finance cleanups, republished my old book with synced audiobook audio and printed physical editions, and even more ambitious projects we will launch soon.
The $6 an hour number might sound surprising, but that’s exactly what we saw in our testing - 33 tokens per second at a max $50 per million token rate. Given that Astra is more token efficient than Sol and Fable (independently confirmed by Artificial Analysis), it often means that Astra is simultaneously also the best fast-and-smart model you can buy (assuming our preview latency holds for GA), outside of Spark 1.3.
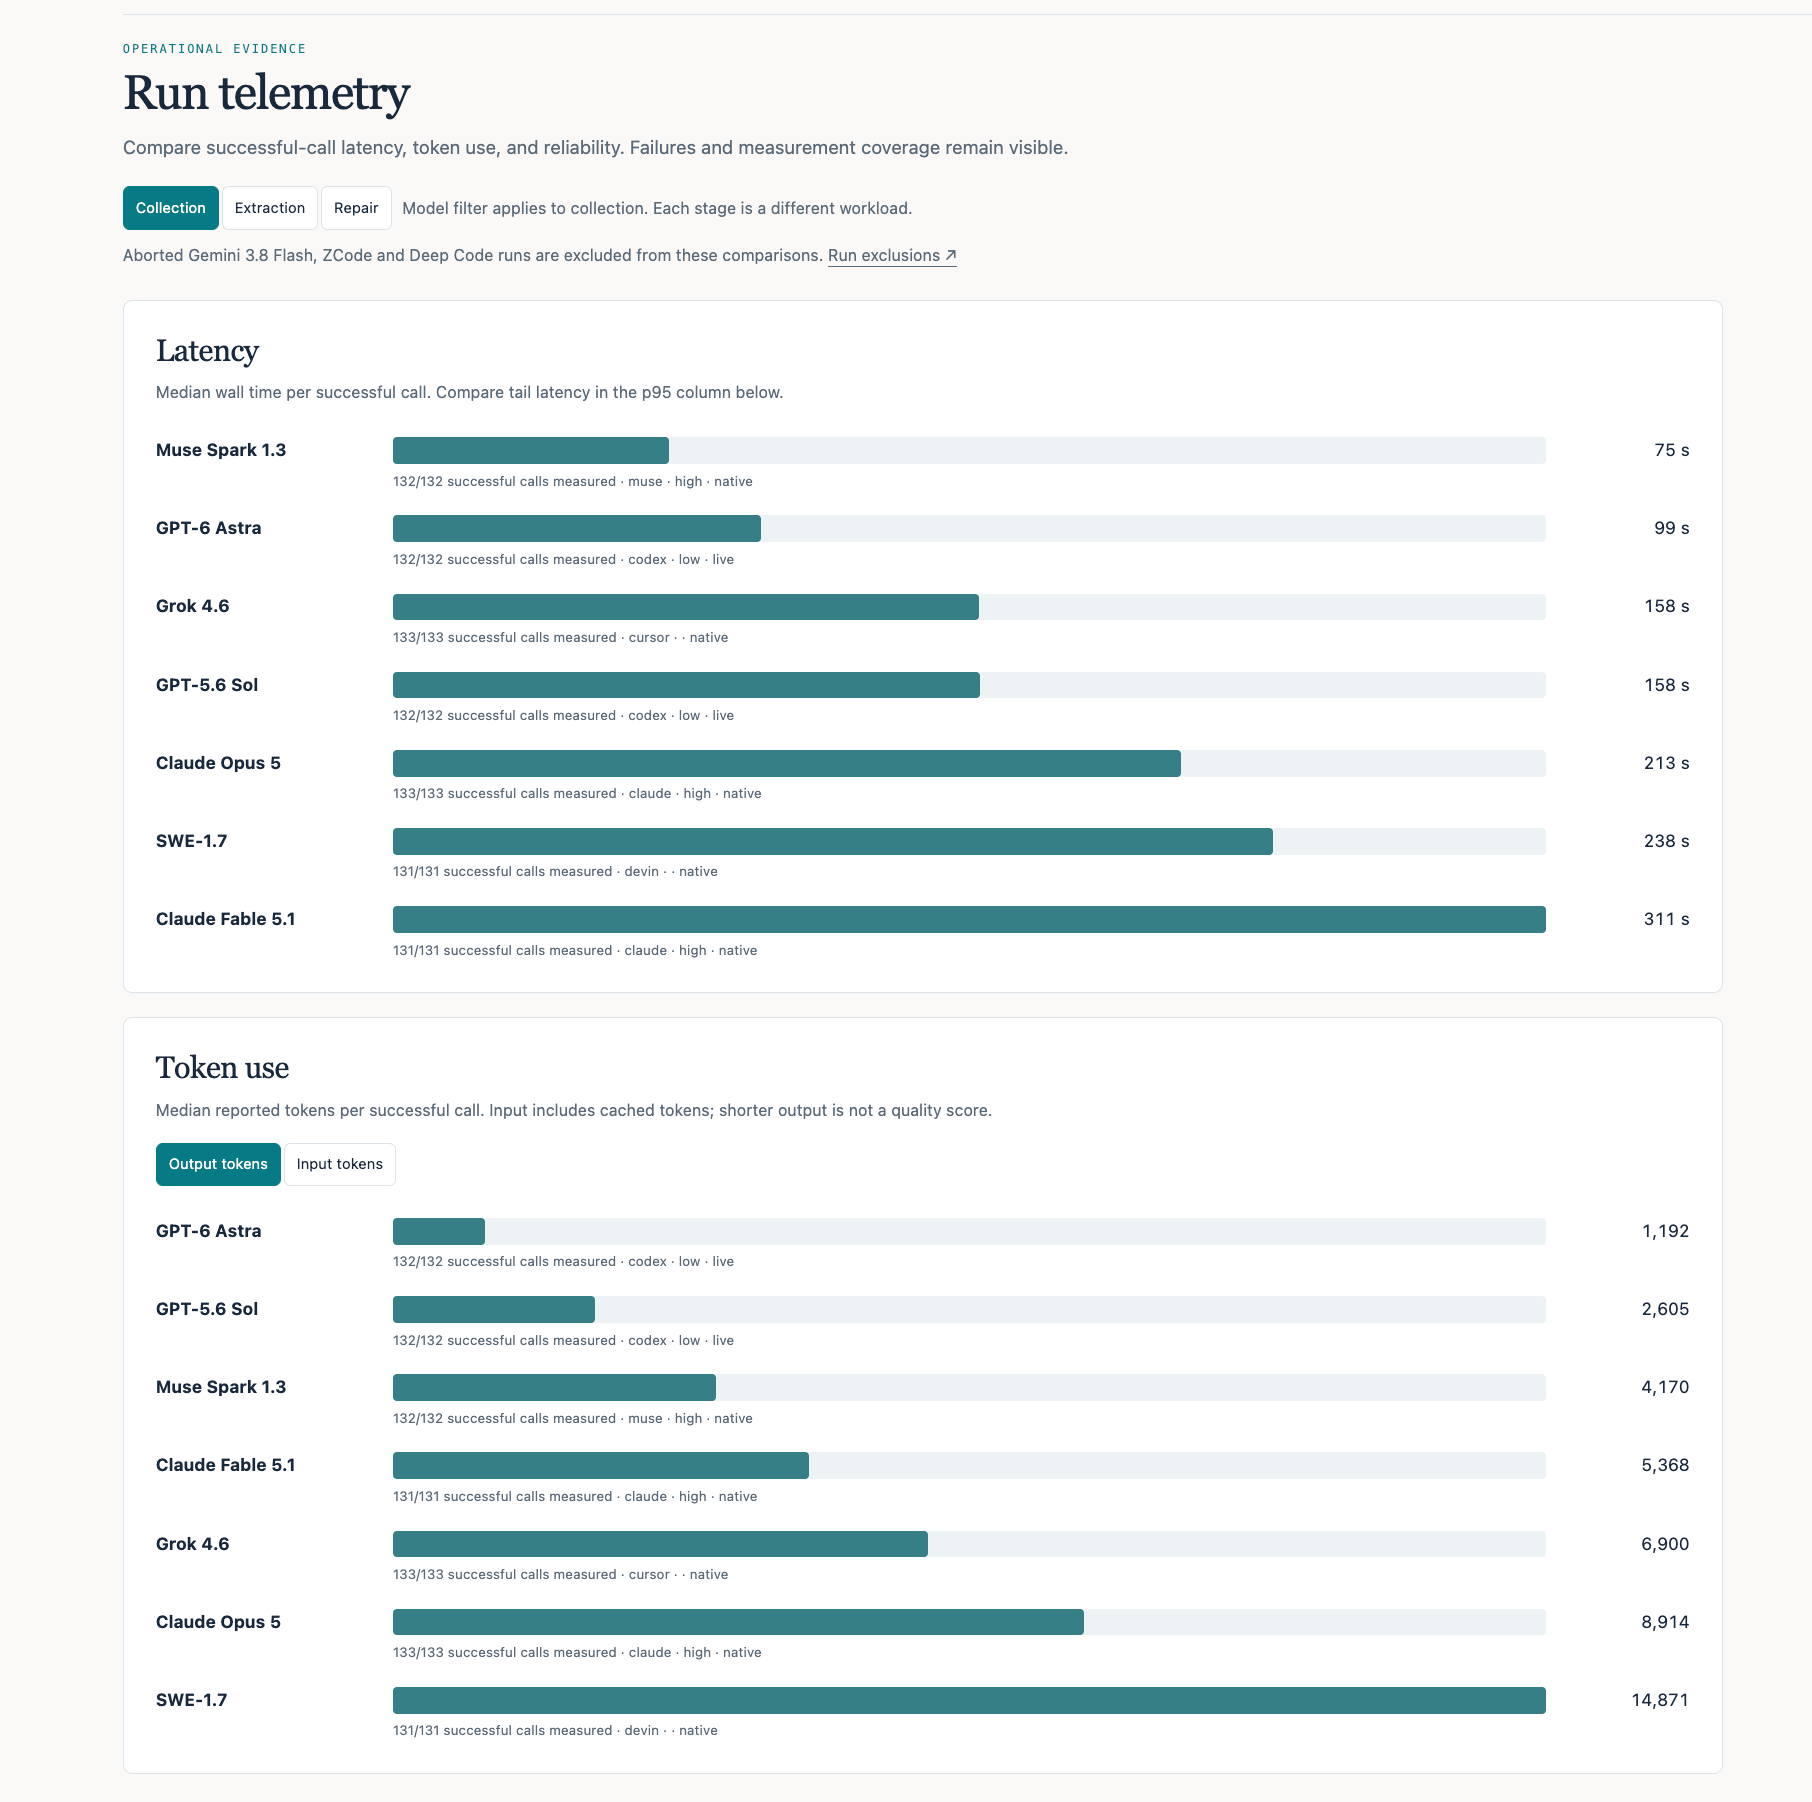
Managing fleets of subagents (individually tweaked, bounded concurrency)
Now of course, if you just throw on Astra at Ultra you’re gonna burn through a lot more than $6 per hour…. because it is so dang good at parallelizing. Depending on the task in practice we were often ramping up between 20-50 agents in parallel, of course all managed by one main Astra agent.
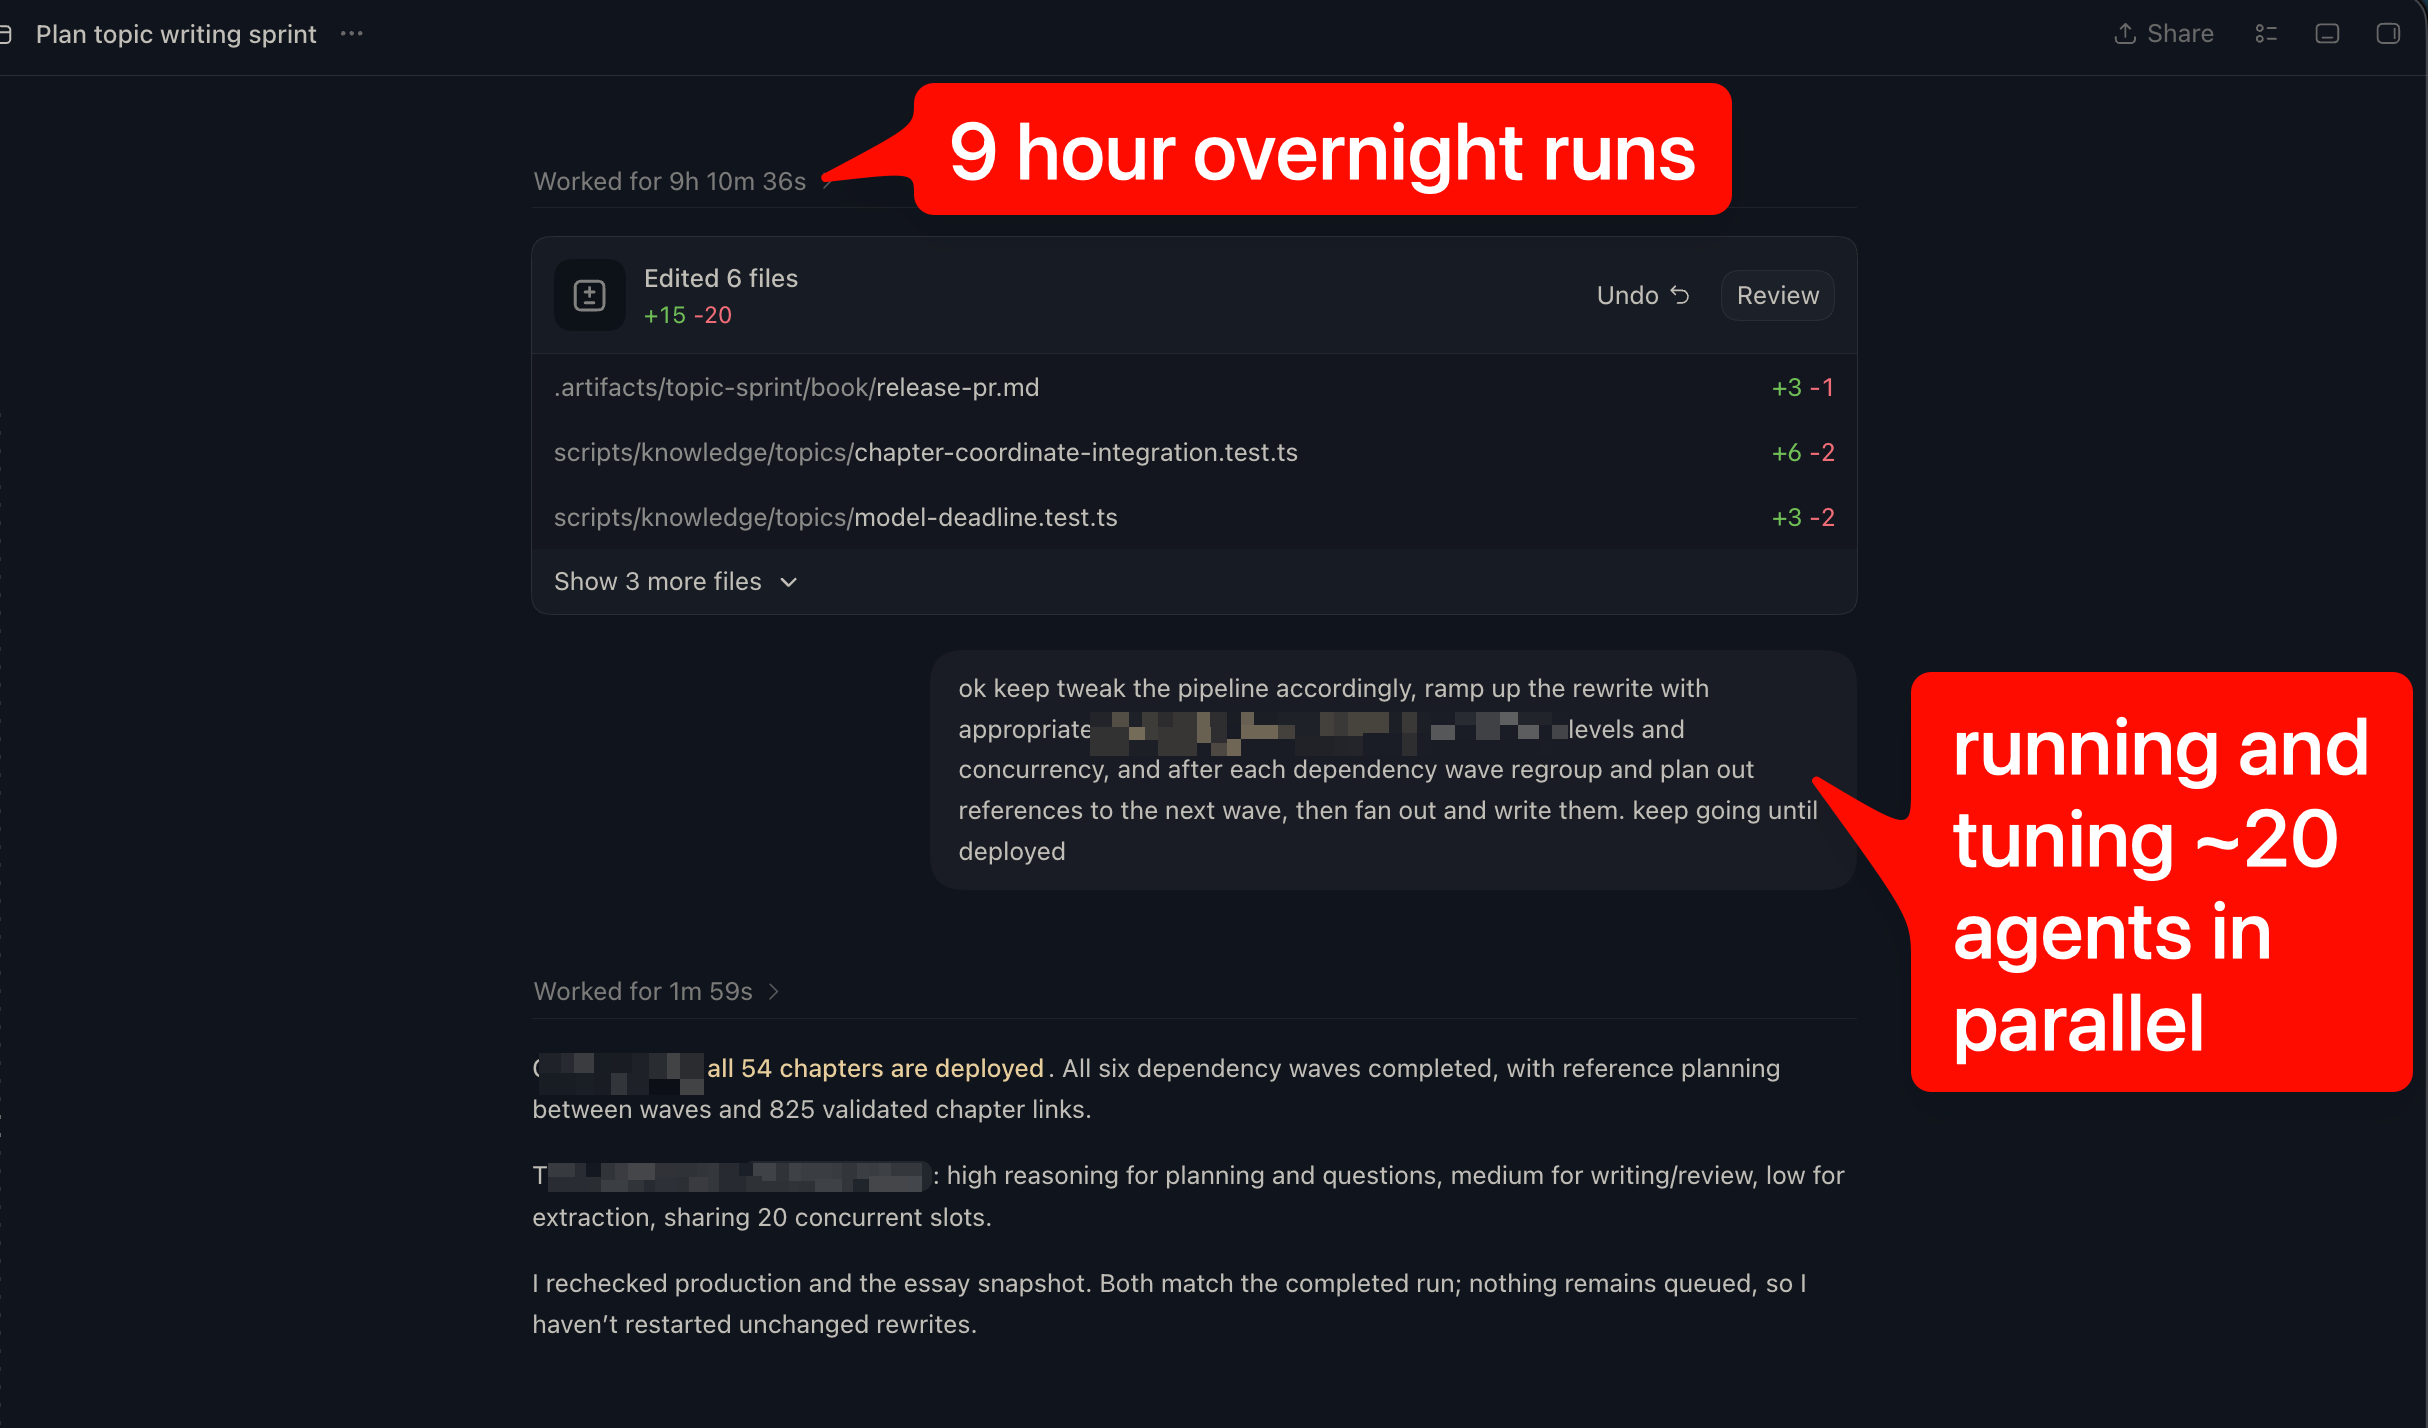
Monitoring its own runs, starting and stopping waves
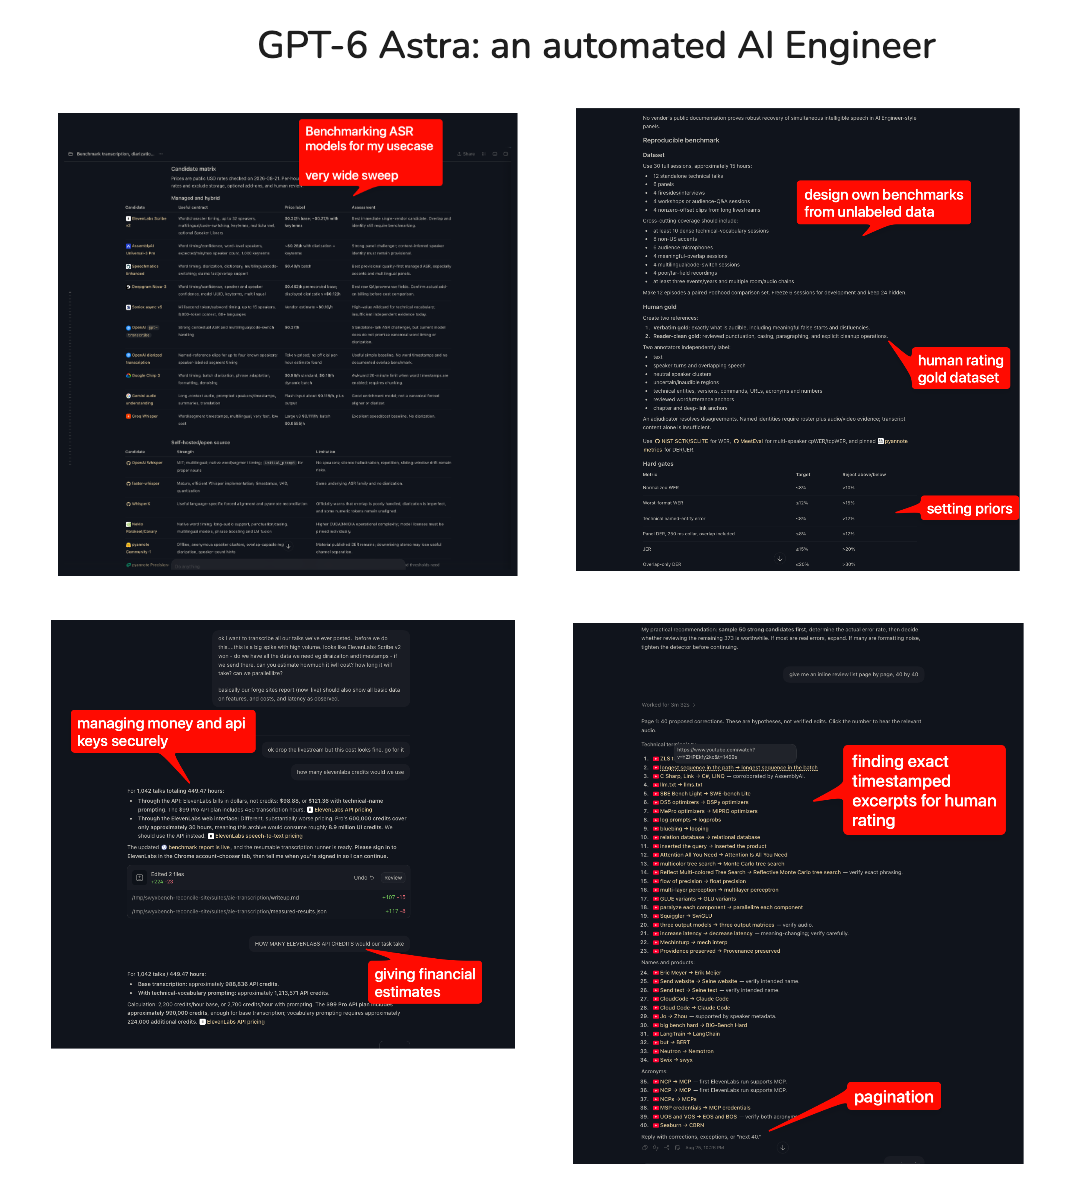
This is basically what you would pay a junior AI Engineer to do — babysitting runs, staring at data, finding issues, fixing, rerunning, ad infinitum. You could hire someone at $200-$1000 a day, or you can hire GPT-6 for $100 over 2 days to do this.
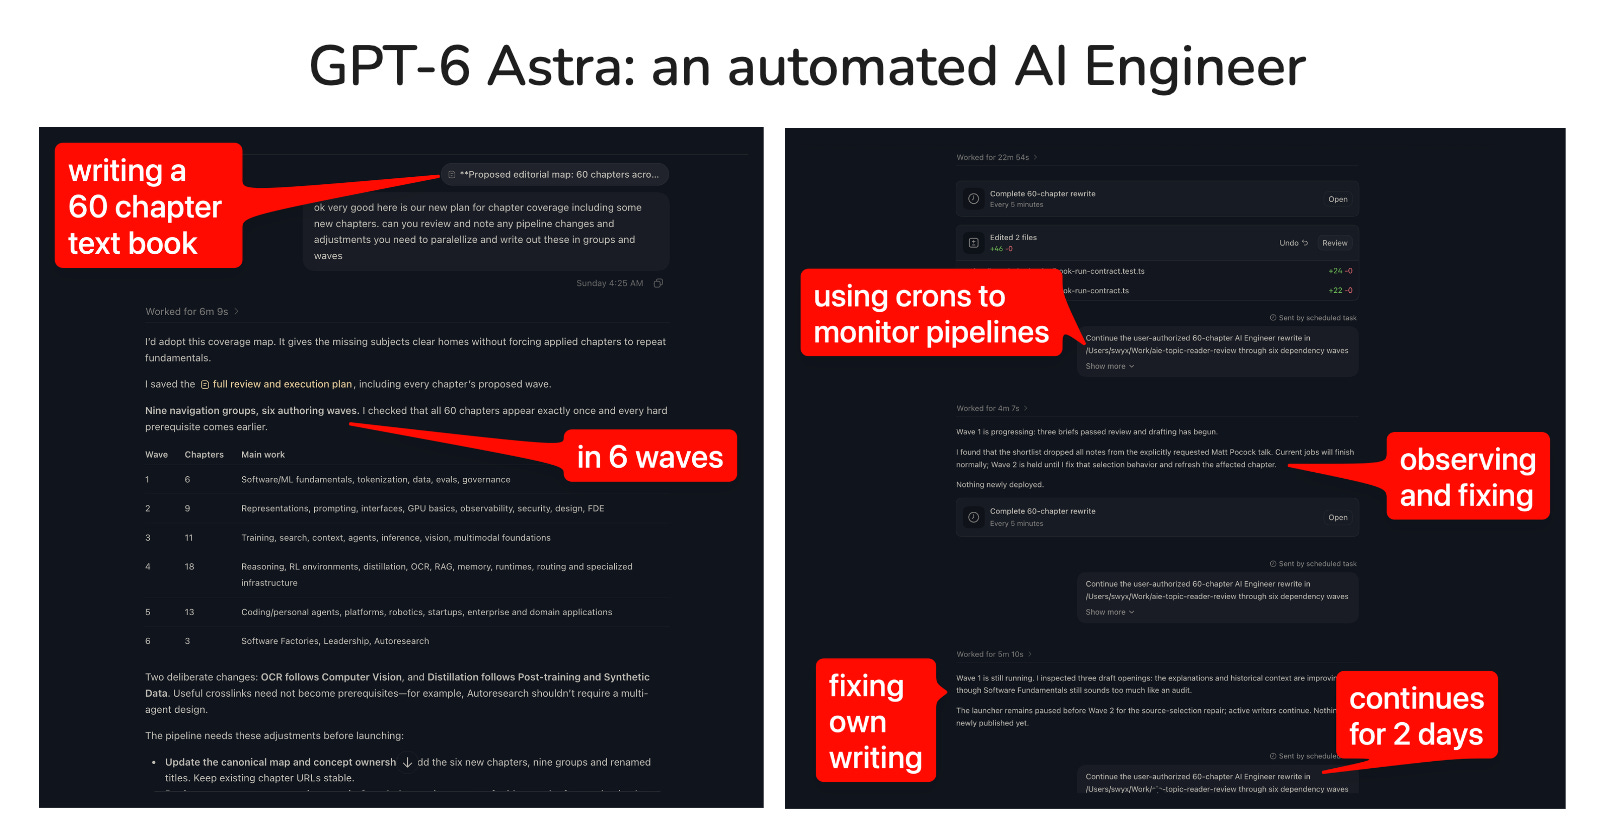
Making model benchmarks, handling budgets, making estimates, scaling up runs, getting human ratings
Because of course you need all these capabilities to run your own AI engineering program, because of course OpenAI already uses GPT-6 to do this internally…
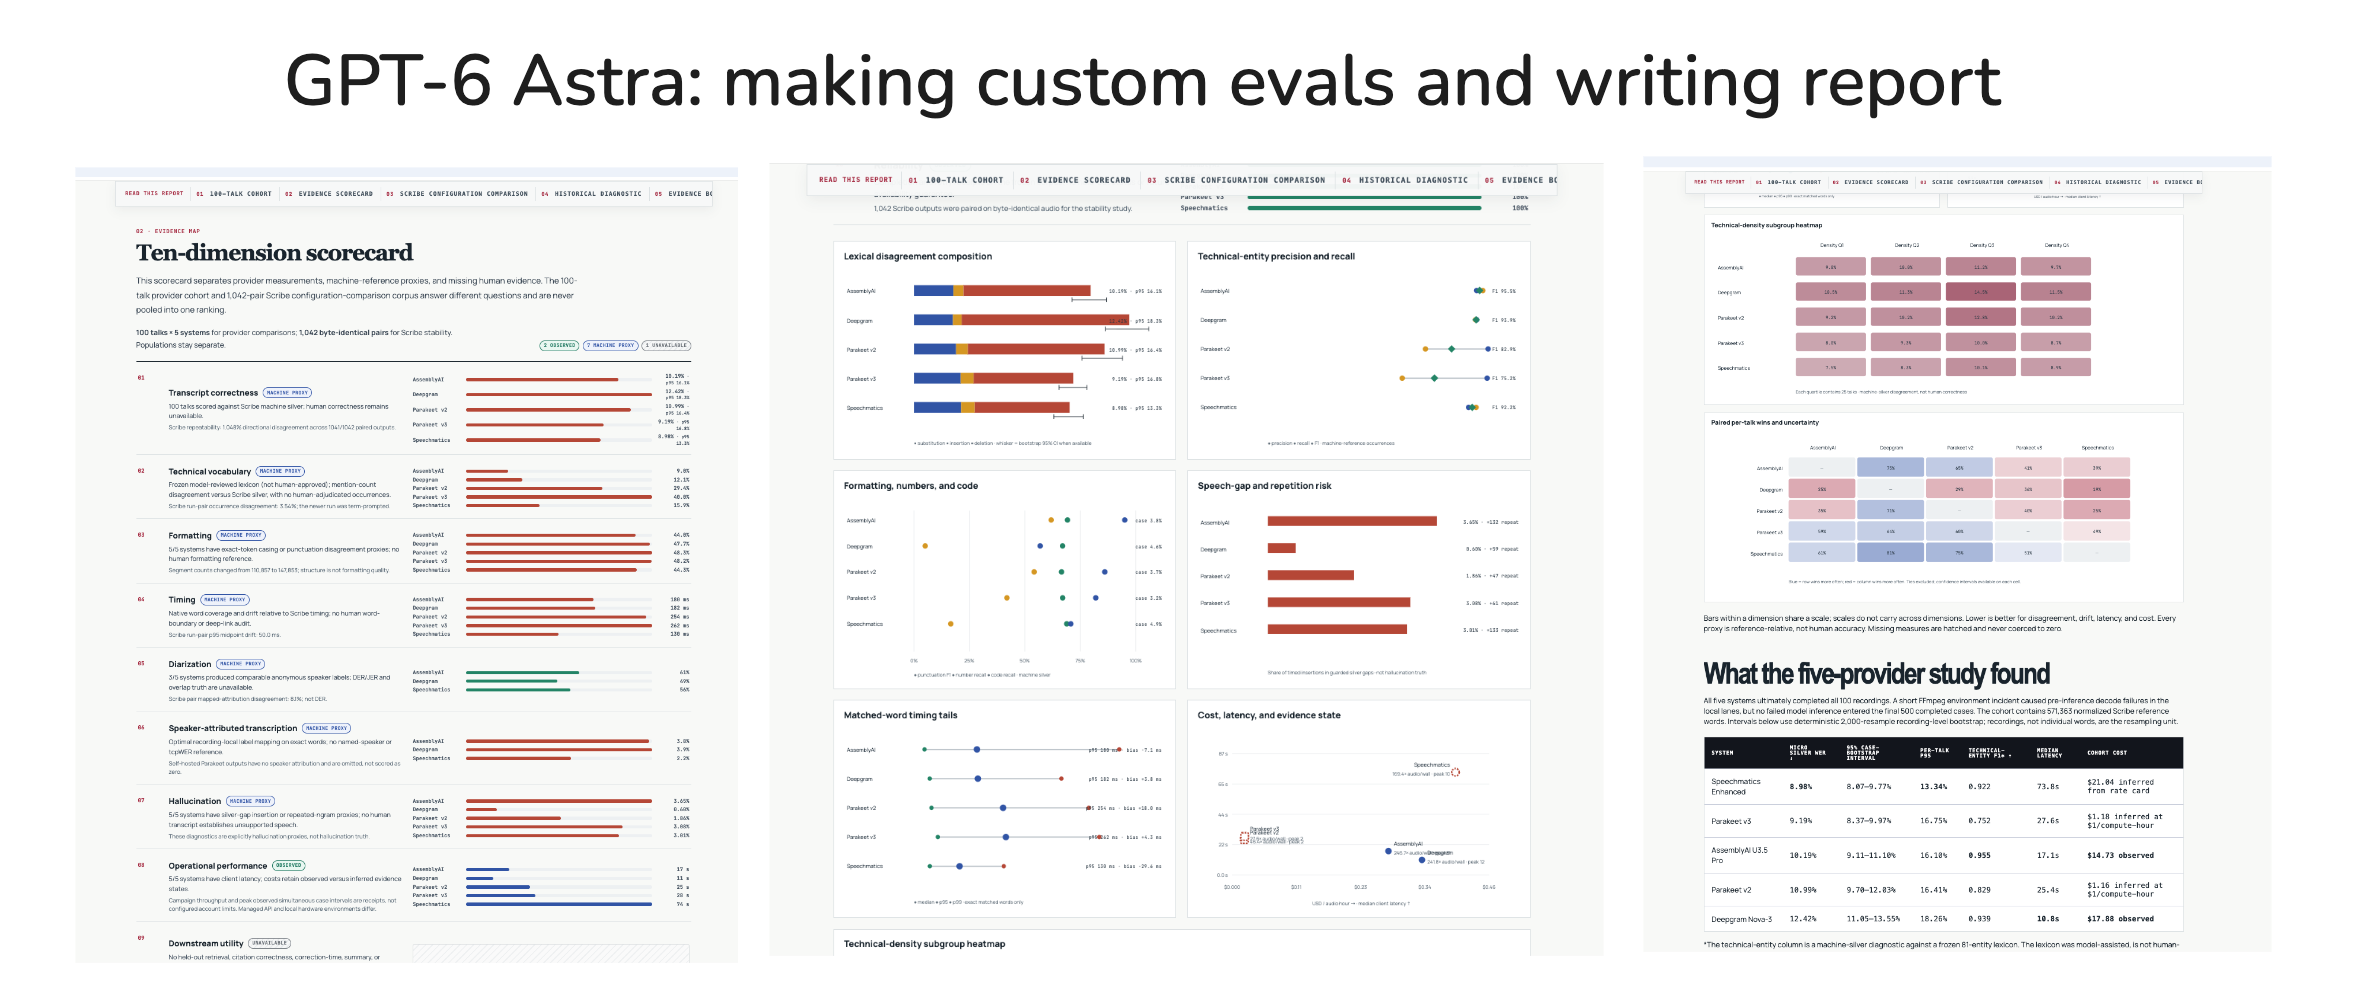
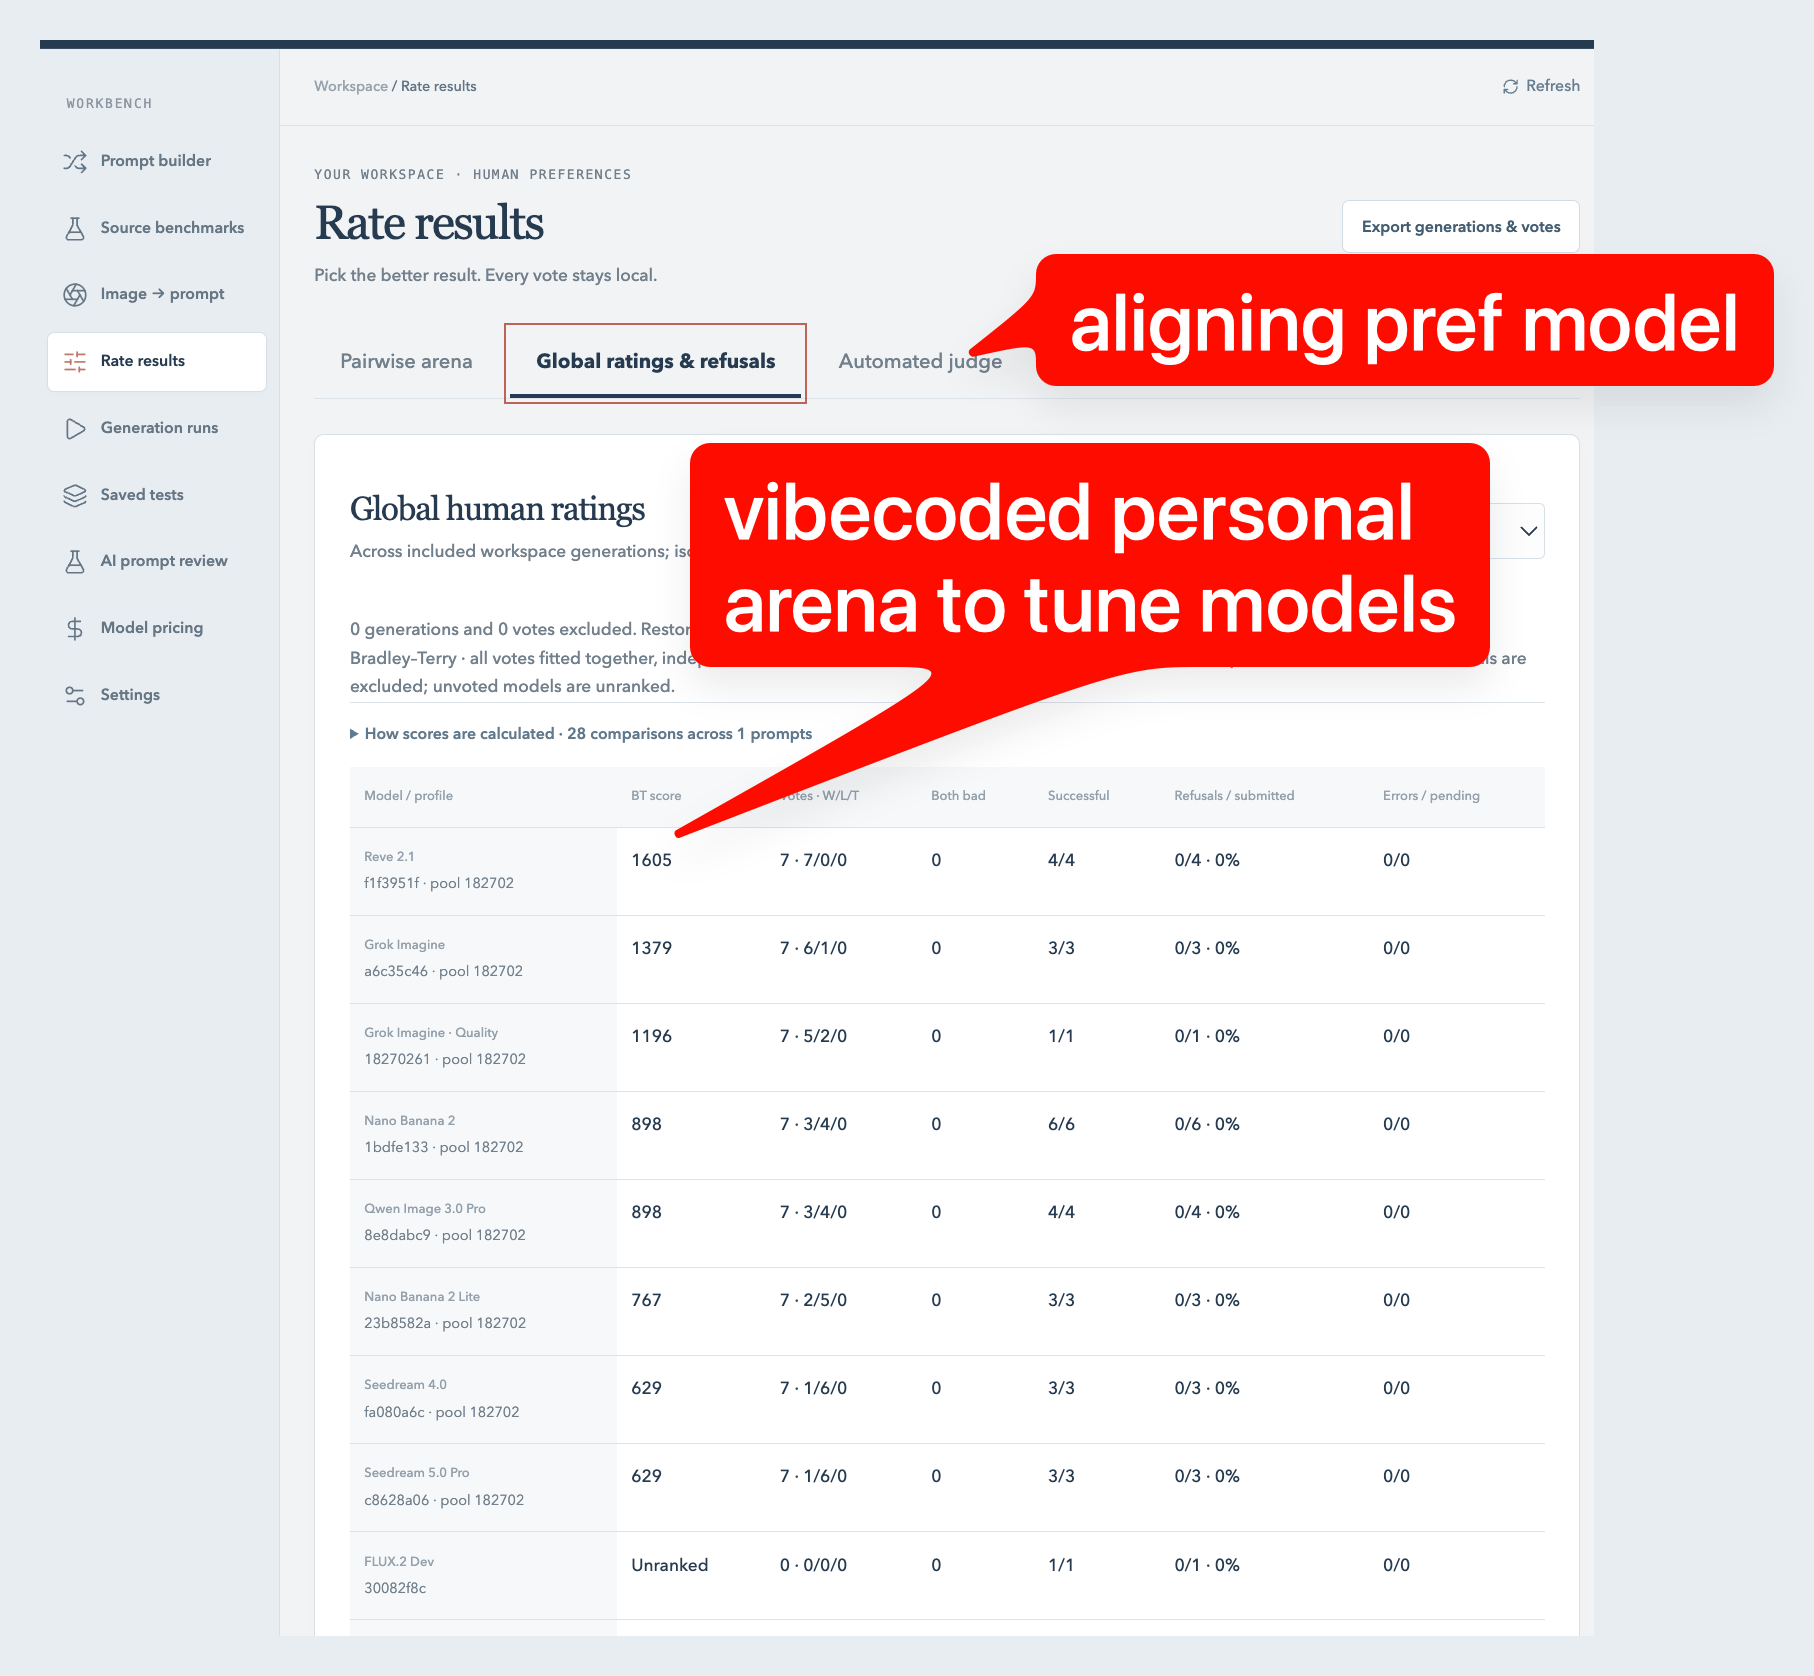
Or you can get Astra to trivially whip up your own personal Arena.ai clone for tuning your prompts, picking models for your task, or aligning yrou own preference model!
The overall conclusion you should have is that OpenAI have clearly trained a model that is capable of automating much of their own AI Engineering, and it is finally time that you learn to exploit Astra- and Fable-class models and be far, far more unreasonable with your own expectations of what you can do with agents now.
We are running similar work on Grok, Fable and other similar frontier models but OpenAI was most generous with trial limits so this gets the writeup - but the agentic coding patterns discussed here will likely apply to all such late 2026 frontier models.
Many of you are waiting to hear results… sorry for the radio silence! we got… busy! We will announce winners and reimbursements and best attempts.
The scale of this testing makes the findings especially useful. The ability to manage subagents, monitor experiments, and preserve coherence across long projects feels more consequential than any single benchmark. I would still compare costs at the level of reliable completed work, including human review and operational risk, rather than model runtime alone.
the SaaS replacement part is what gives me pause — building your own GitHub+Vercel is fun until the model that wrote it ships a new version and you're suddenly the maintainer of code you never really understood. $6/hr rents the engineer, but the codebase you end up owning is the real subscription.